Skip to content

The platform for physical AI

Capabilities

A few of the things you can do in just a few lines of code

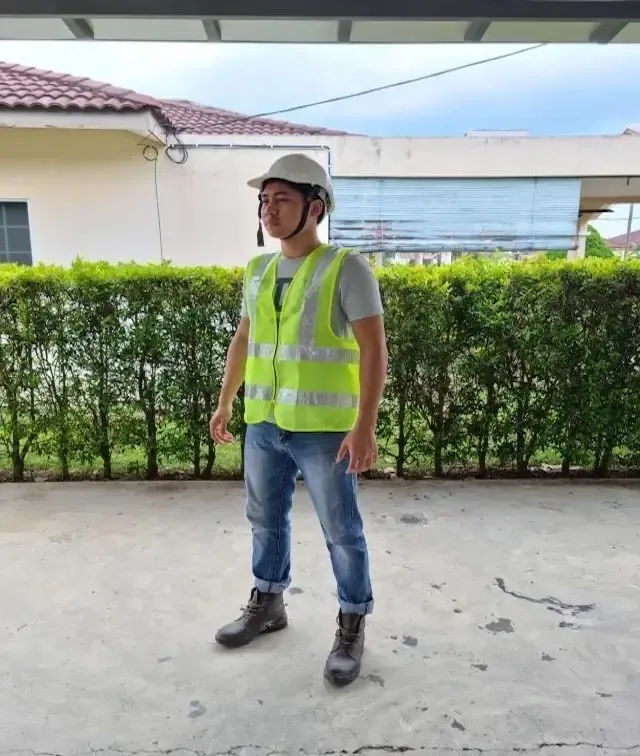
Construction worker wearing a helmet and high visibility vest, with the head region marked Focus.

Focus (Zoom + Crop)

@perceive(model="perceptron-mk1.5", max_tokens=4096, expects="box", tools=True)
def detect_ppe(frame_path: str):
    return (
        image(frame_path)
        + text(
            "Detect and localize the following PPE: helmets, gloves, closed-toe shoes, and protective eyewear. "
            "For each item, identify all instances with bounding boxes. "
            "If any required PPE is missing for any person, alert me and specify exactly which items are missing."
        )
    )
detect_ppe("construction_site.png")
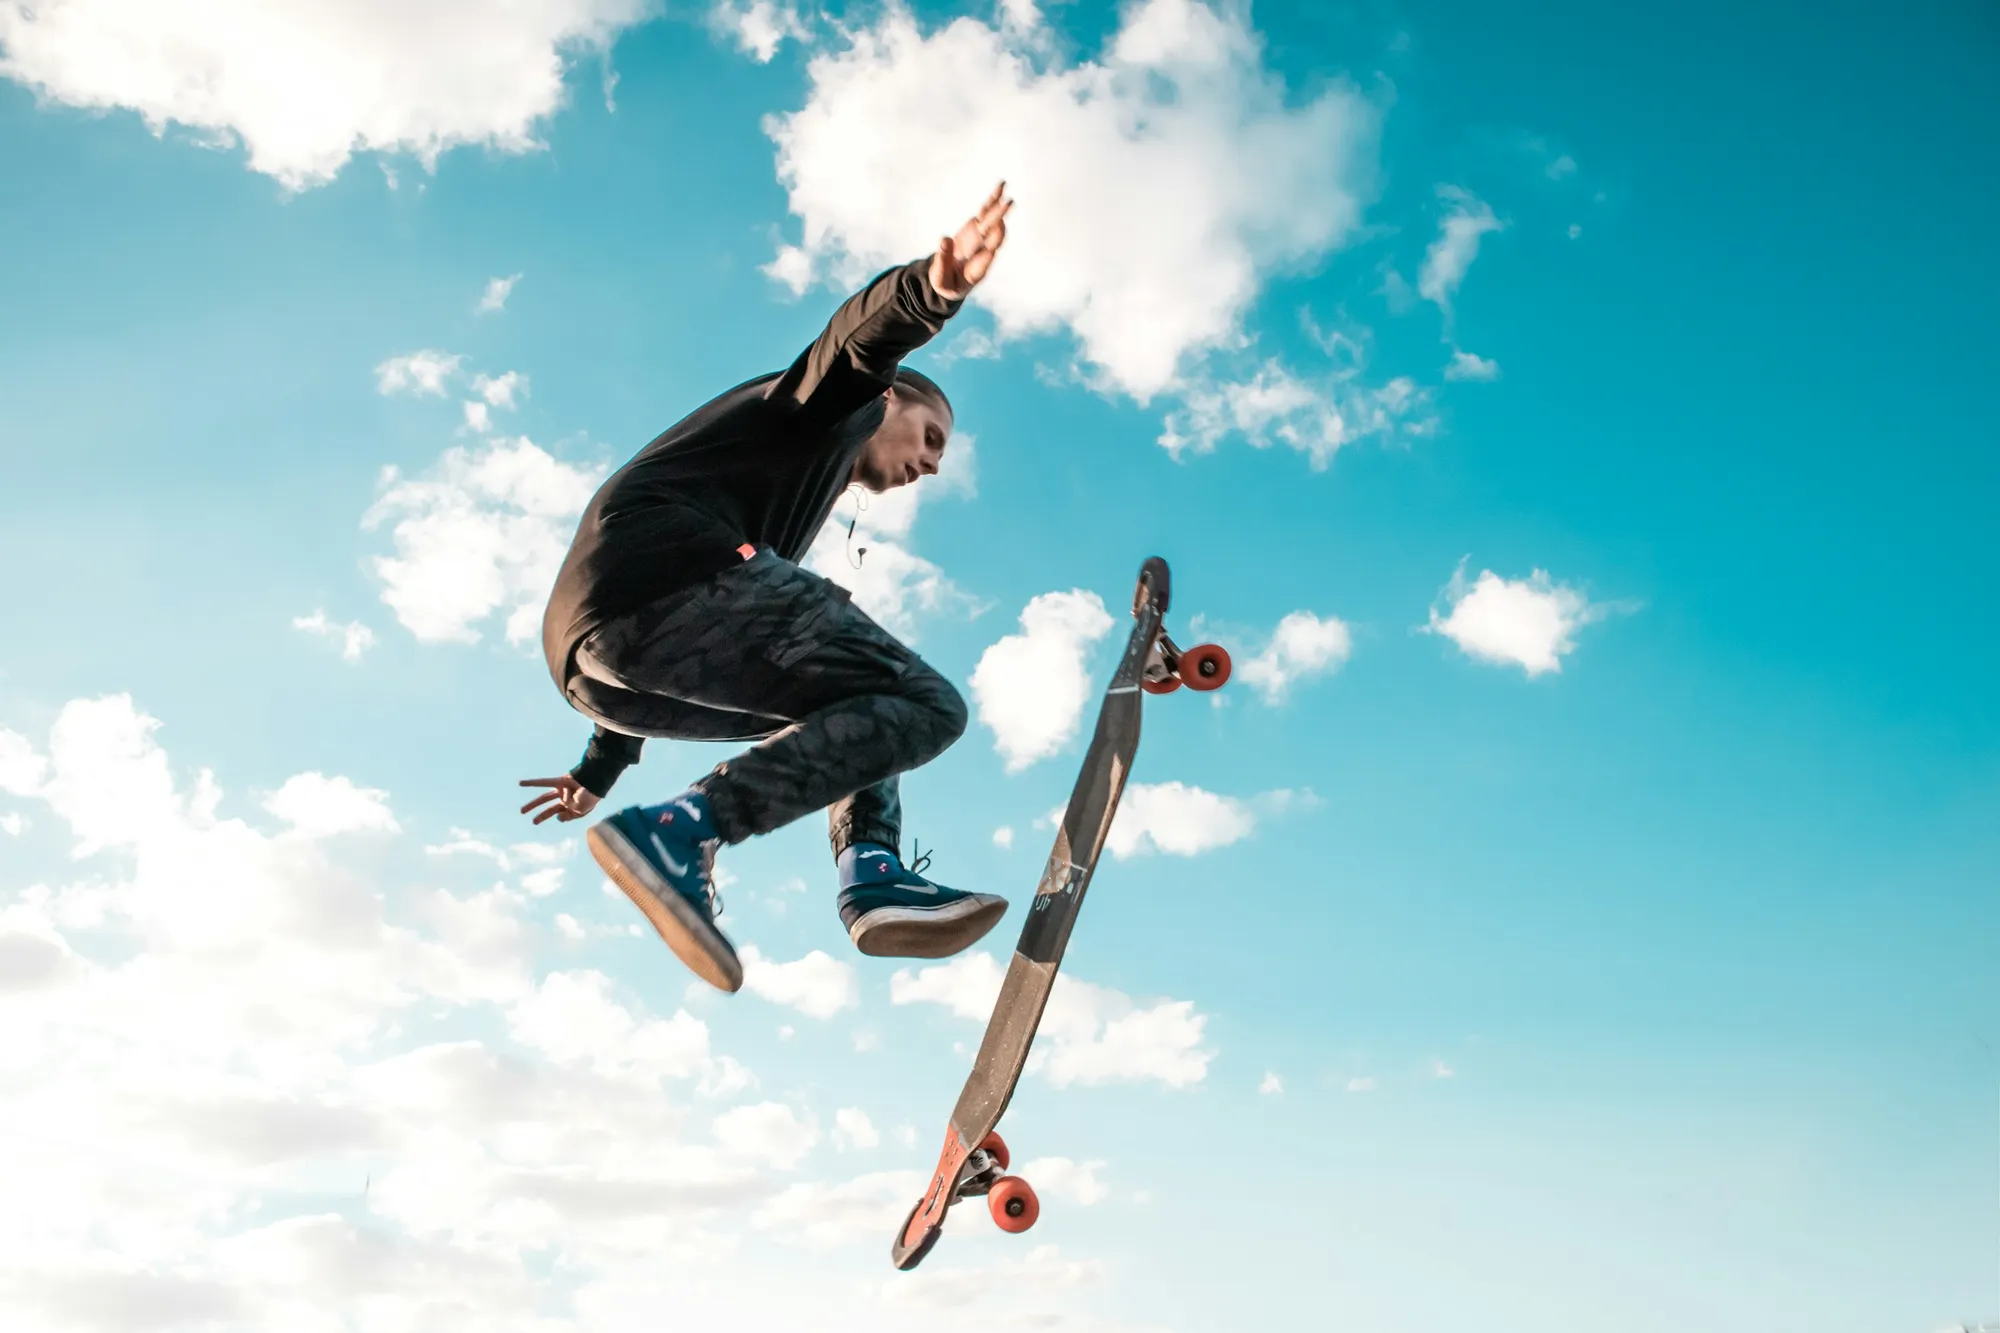
Skateboarder mid-air against a blue sky, outlined as the focal point of the scene.

Conversational Pointing

text_prompt = "Identify single focal point of the scene. Be concise."

@perceive(model="perceptron-mk1.5", expects="box", allow_multiple=True)
def focal_point(frame_path: str):
    scene = image(frame_path)
    return scene + text(text_prompt)

focal_point("skate.jpg")
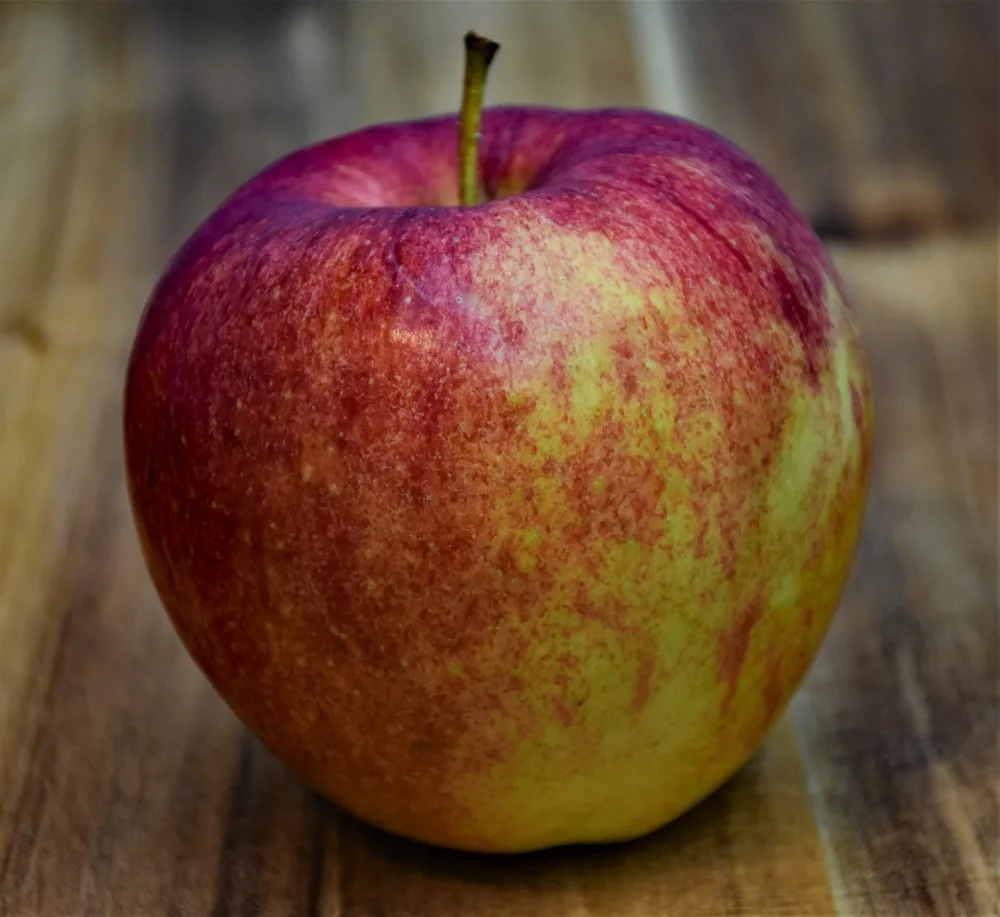
Reference apple beside a produce scene, with every matching apple outlined as category 1.
Reference example: a close-up of a single red apple.category_1

In-Context Learning

@perceive(model="perceptron-mk1.5", expects="box", allow_multiple=True)

def evaluate_produce():
    apple_example = "apple.jpg"
    target_scene = "fruits.webp"
    return (
        apple_example
        + text("This is Category 1. Action to take: cut into slices.")
        + target_scene
        + text(
            "For every instance of Category 1, output a bounding box labeled with the action to take."
        )
    )

evaluate_produce()
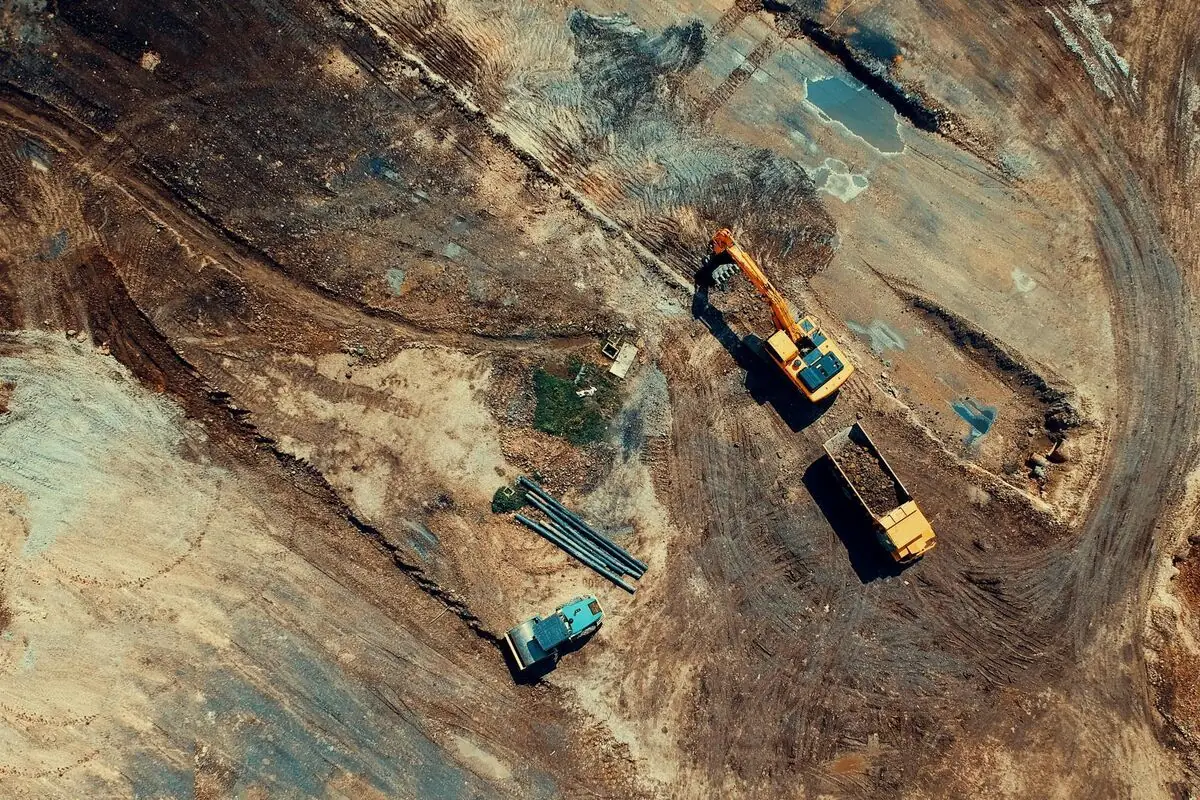
Aerial view of a construction site with three pieces of heavy equipment bounded and labeled.

Object Detection

detect(
    image_obj="construction-site.jpg", 
    classes=["heavy equipment"]
)
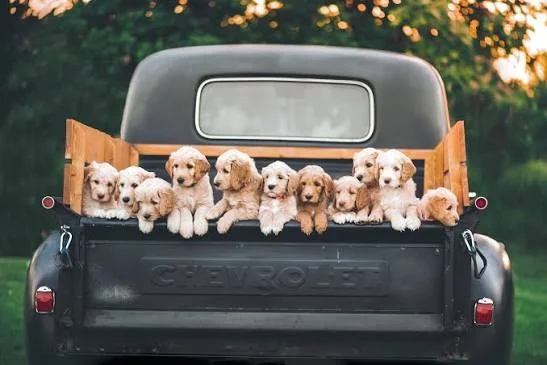
Eleven puppies in the bed of a pickup truck, each marked with a numbered point.

Counting

text_prompt = "Help me count the puppies. Point to each."

@perceive(model="perceptron-mk1.5", expects="point", allow_multiple=True)
def count(frame_path: str):
    scene = image(frame_path)
    return scene + text("Help me count the puppies. Point to each.")

count(puppies.jpg)
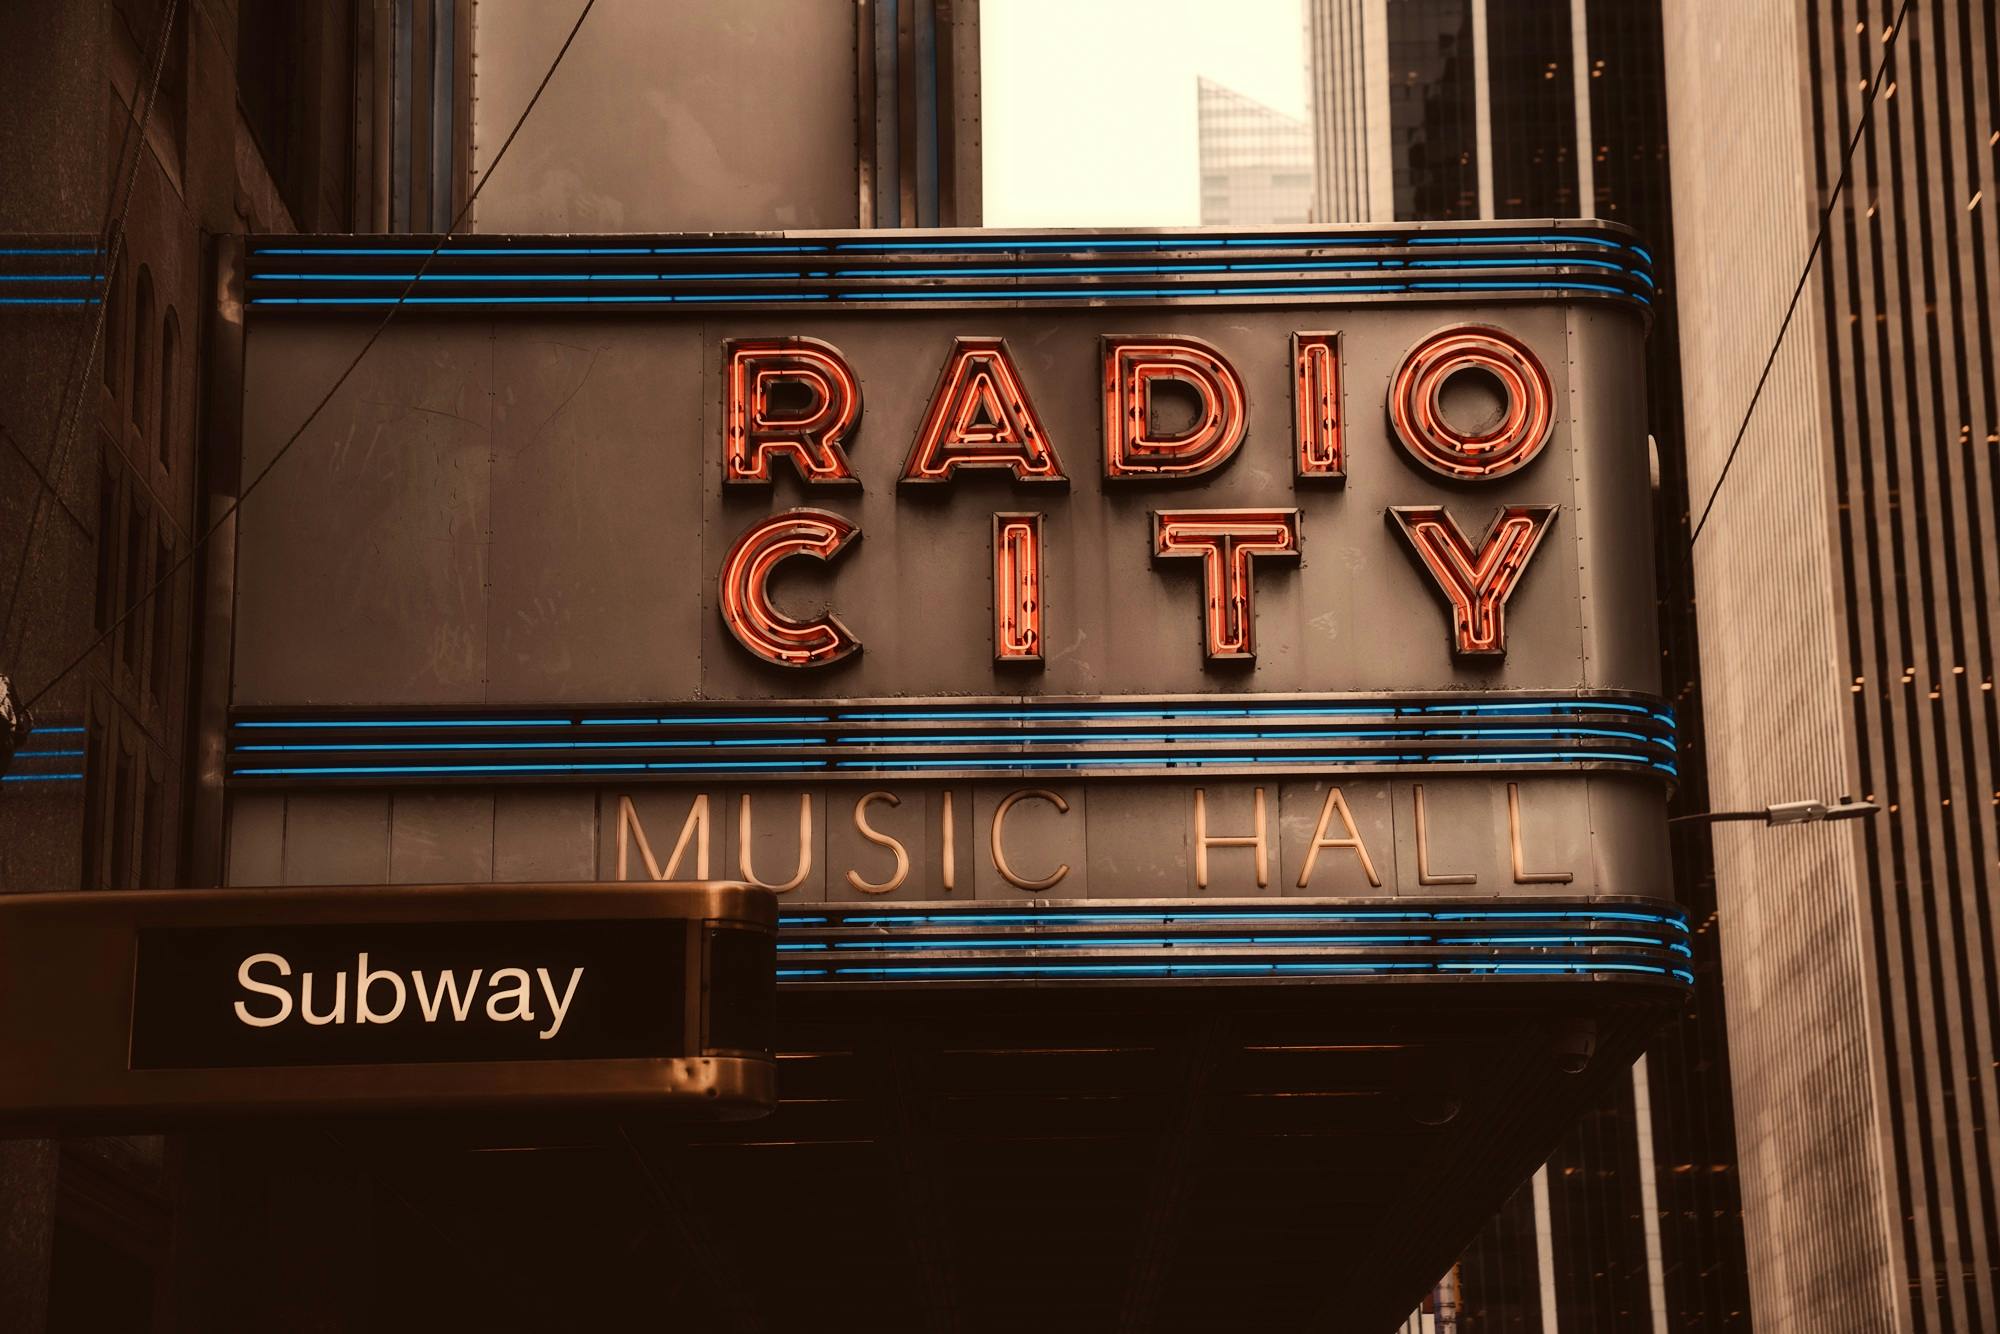
Radio City street sign for optical character recognition.

Optical Character Recognition

ocr(
    image_obj="radio-city.jpg", 
    prompt="Read any signs."
)
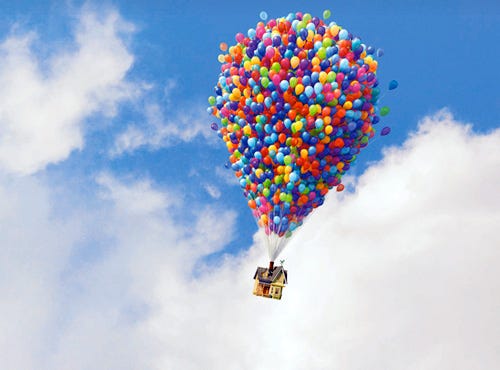
House lifted by colorful balloons for an image caption.

Captioning

caption(
    image_obj="up.jpg", 
    expects="text", 
    style="concise"
)

Cost Calculator

$0.1500/1M in · $1.5000/1M out

Perceptron Mk1.5

Total per request

$0.0025

15,749 tokens / request

2 fpsdynamic sample rate · 120 frames
Prompt19 tok~$0.0000
Video in15,600 tok$0.0023
Output130 tok$0.0001

120 frames, each at 640×416.

Video

Prompt

Video is sampled at up to 2 fps into a fixed patch budget, so longer clips add frames only until that budget fills — then tokens plateau.

cost = (tokens / 1M) × rate — token counts mirror the Mk1.5 tokenizer: images scale with resolution up to a per-image patch budget, and video is sampled at up to 2 fps into a per-request budget, so video tokens plateau as frame rate and duration climb. Planning estimates only; exact counts come from the SDK.

Get started today